Reliable by Design. Ready to Recover.
Cloud & Service Reliability
How digital services are monitored, maintained, backed up, recovered, and communicated when issues occur.
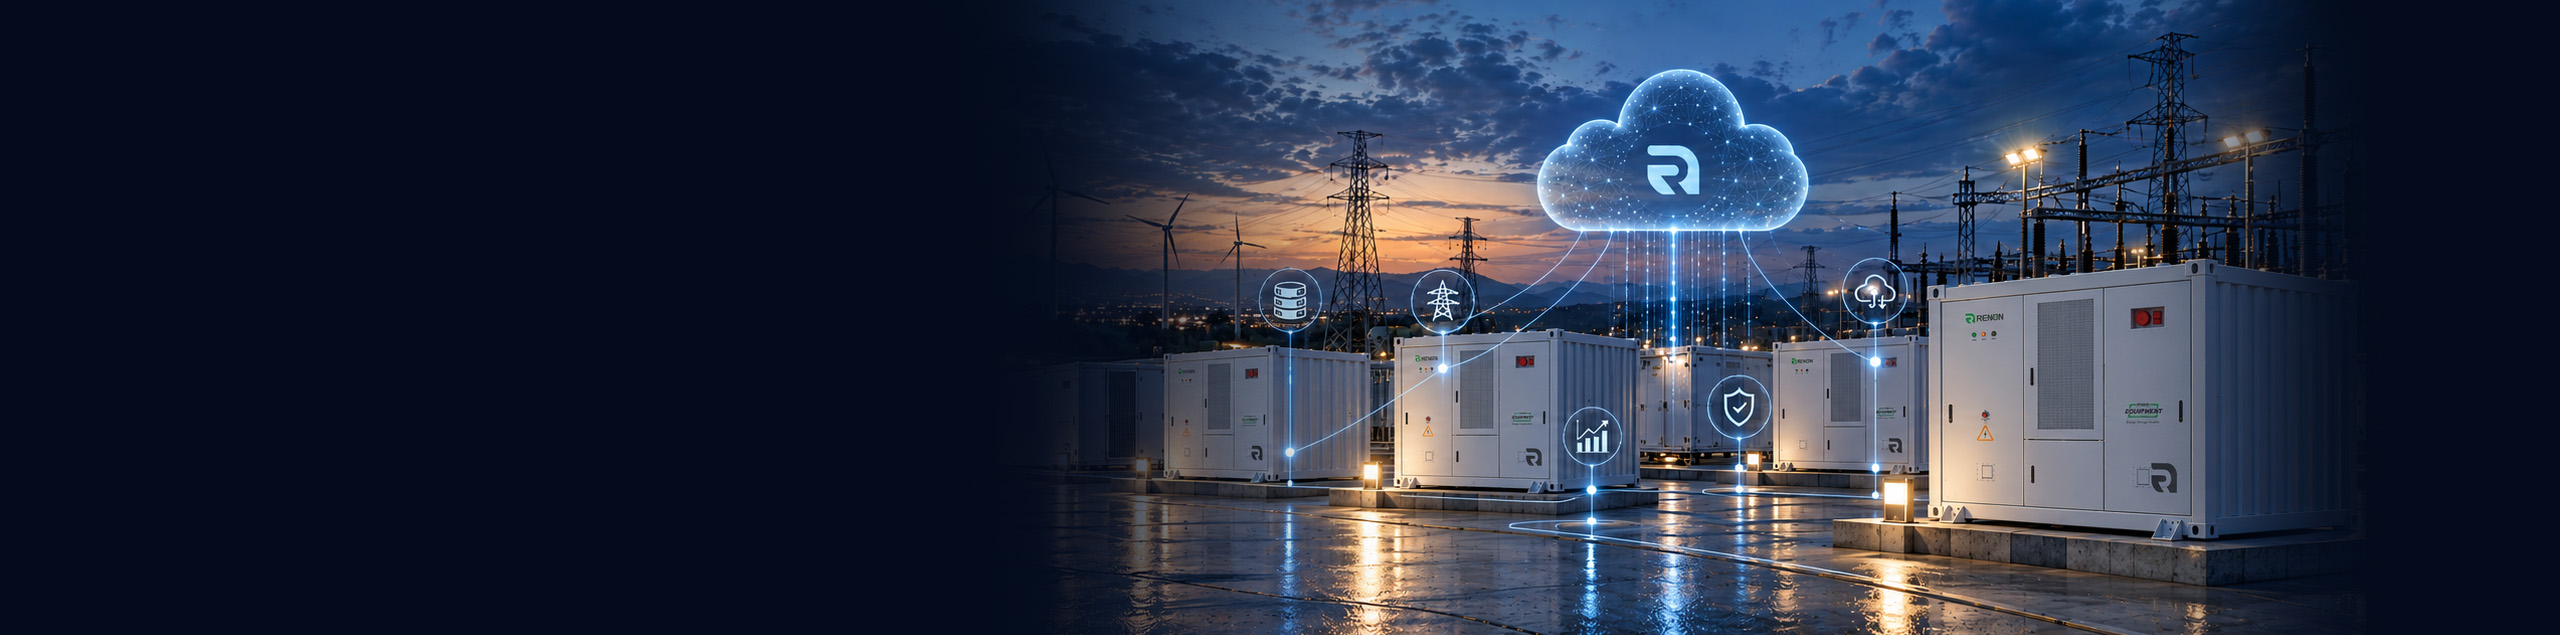
Reliable by Design. Ready to Recover.
Digital reliability goes beyond being simply online or offline.
Renon Power manages digital services across architecture, monitoring, local and cloud boundaries, backup, recovery, change management, disaster recovery, and incident communication.
Architecture
Monitoring
Edge Boundaries
Backup & DR
Change Control
Incident Comms
SYSTEM ARCHITECTURE & SEGREGATION
Digital Services & Engineering Boundaries
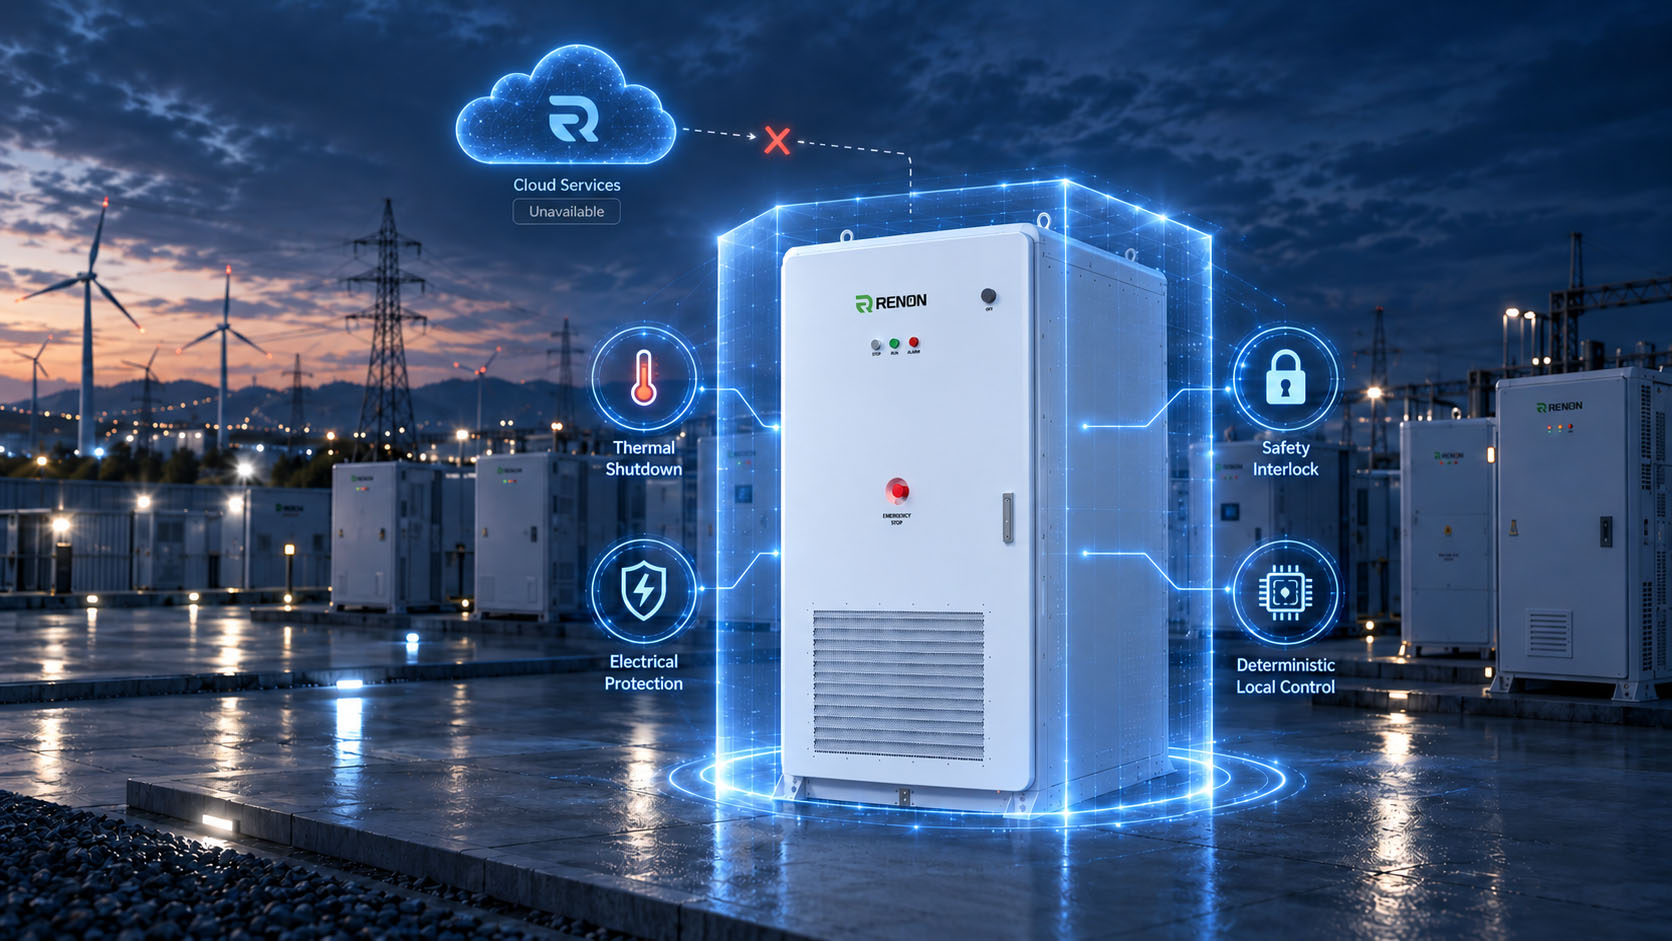
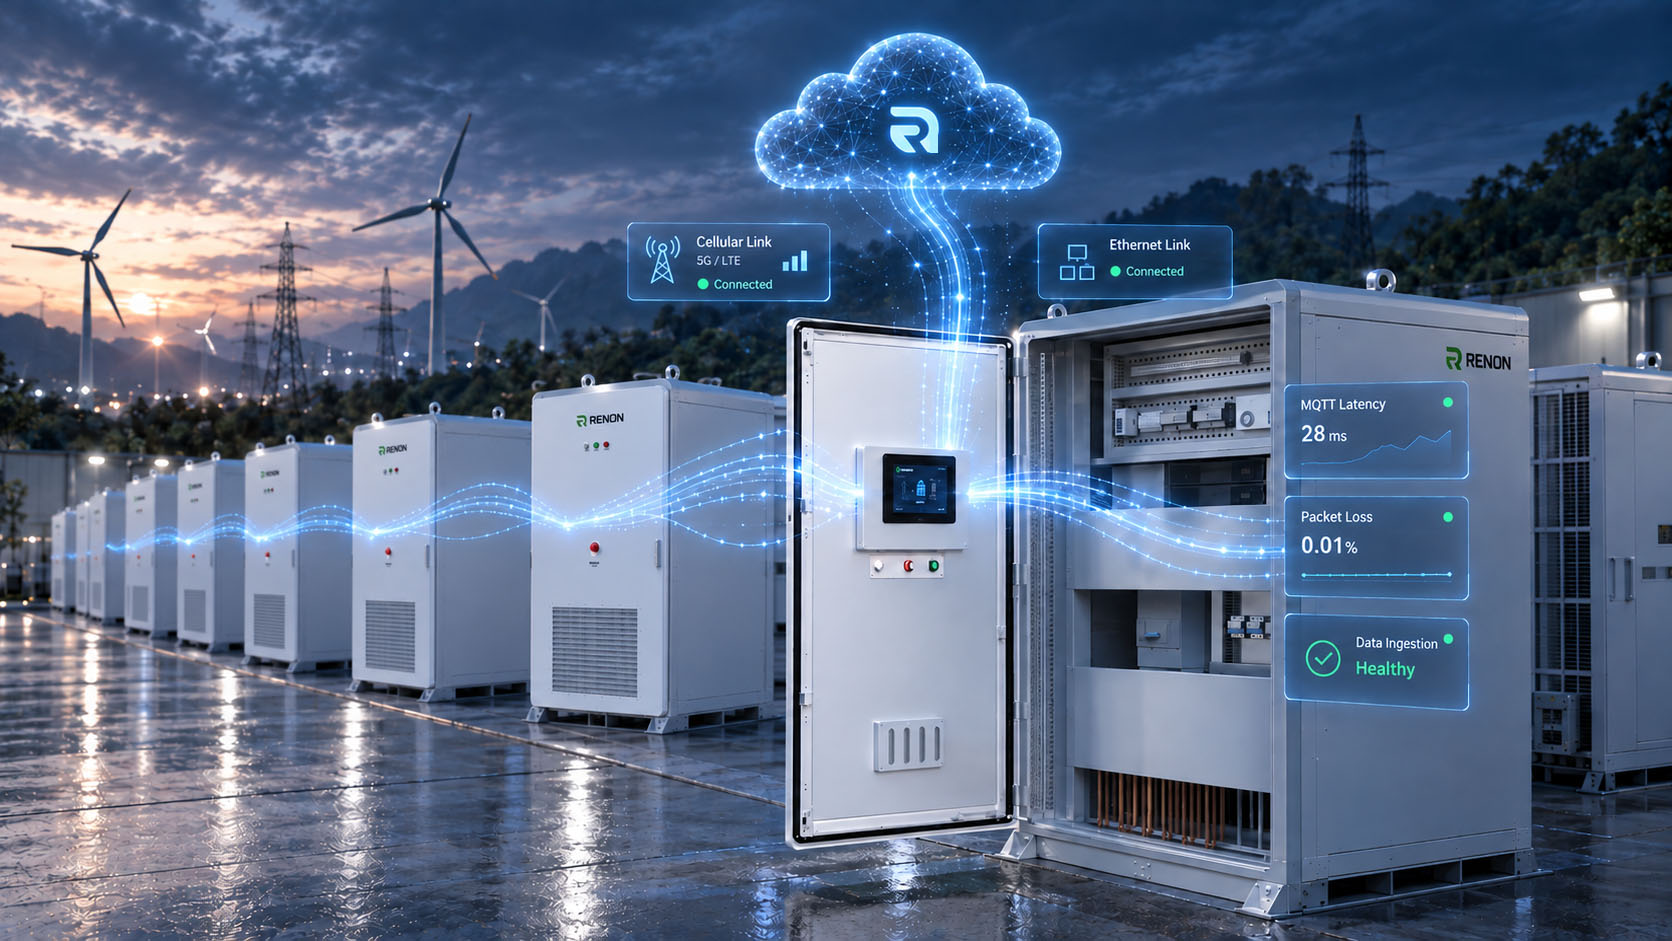
Critical physical safety, thermal shutdown, and electrical protection functions maintain strict deterministic execution locally at the edge, fully decoupled from cloud availability.
Critical Local Safety & Controls
Autonomous protection layer executing directly on dedicated microcontrollers, BMS, and PCS controllers without requiring internet or cloud connectivity.
Cloud Services, Telemetry & Portal Ecosystem
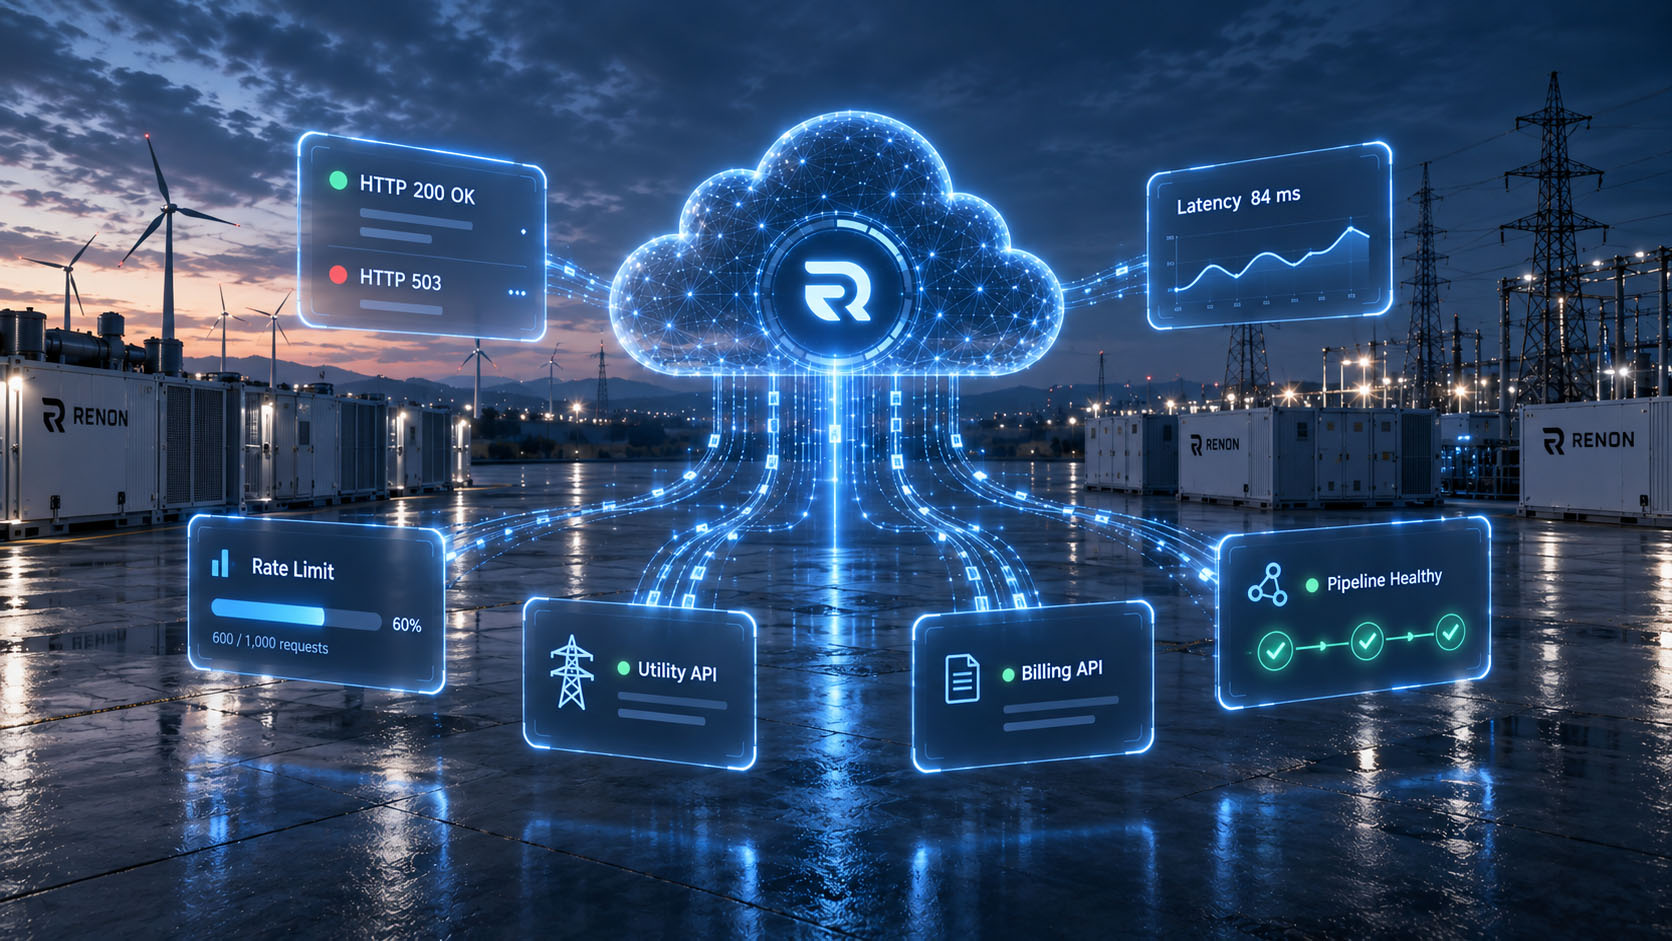
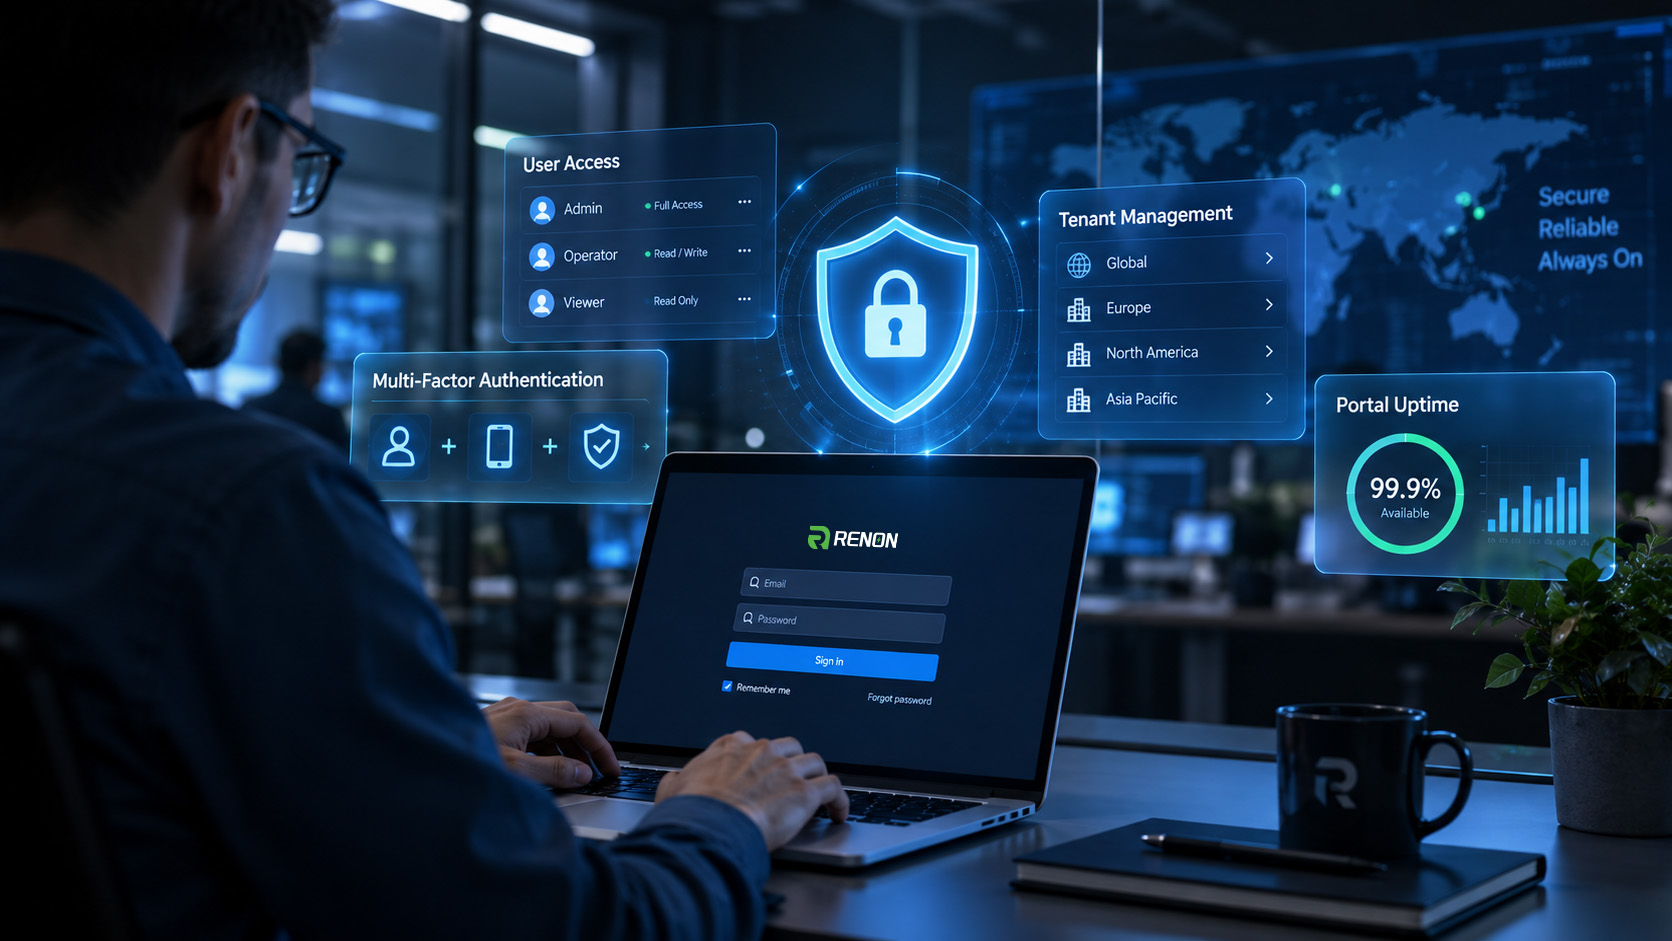
Depending on the product, customer tier, and service scope, our enterprise cloud platform delivers scalable fleet analytics, portals, and diagnostics.
Backup, Recovery & Business Continuity
Backup and recovery arrangements are established according to the criticality of applicable data and services. For mission-critical digital systems, recovery priorities, cross-region replication, and failover responsibilities are formally governed.
Change & Maintenance Management
Material modifications to cloud infrastructure, databases, telemetry ingestion queues, and customer APIs are evaluated and tested in staging environments with mandatory rollback and recovery procedures.
Reliable by Design. Ready to Recover.
Review digital service architecture, real-time health telemetry, and disaster recovery standards across the Renon ecosystem.
Incident Communication & Service Levels
Triage & Impact Assessment

Automated anomaly detection identifies affected infrastructure components, client fleets, and geographic regions.

Containment & Failover

Execution of automated traffic rerouting, redundant cloud failover, and queue scaling to protect live telemetry.

Broadcast & Status Updates

Periodic status page updates and direct notifications to designated enterprise contacts regarding recovery milestones.

Root Cause Analysis (RCA)

Comprehensive post-incident analysis detailing timeline, root cause, preventative remediation, and SLA review.

Share